kdn small language models with hugging face transformers library smollm3 feature

Small Language Models with Hugging Face transformers Library + smolLM3

  Contents# Small But Powerful# Why Small Language Models Deserve More Attention# Understanding SmolLM3’s Architecture# Setting Up Your Environment# Loading SmolLM3 and Running Your First Inference# Building a Multilingual Support Ticket Router# Adding Tool Calling to SmolLM3# Fine-Tuning SmolLM3 on Domain Data# Conclusion # Small But Powerful  Running a 70B model in production can be expensive, slow, and, for many tasks, unnecessary. If you’re building …

Small Language Models with Hugging Face transformers Library + smolLM3 Read More »
continual learning remember work.webp

Continual Learning Makes AI Remember Your Team’s Work · Hanh D. Brown

Continual Learning Makes AI Remember Your Team’s Work. The smartest model is still a stranger to your company. Continual learning is the bet that the next gain is not a smarter stranger, but a model that has learned you. continual-learning ai-memory fine-tuning rag model-weights The smartest model in the world is still a stranger to …

Continual Learning Makes AI Remember Your Team’s Work · Hanh D. Brown Read More »

ai infrastructure built on light.webp

AI Infrastructure Runs on Light, Not Just More Chips · Hanh D. Brown

AI Infrastructure Runs on Light, Not Just More Chips. The model you talk to is the tip of the iceberg. Under it sit energy, chips, and miles of light-carrying optics that have to be built somewhere. ai-infrastructure optical-interconnect silicon-photonics ai-factory reindustrialization The model you talk to is the tip of the iceberg. Under the water …

AI Infrastructure Runs on Light, Not Just More Chips · Hanh D. Brown Read More »

kdn 7 best web crawling tools and apis in 2026 feature

7 Best Web Crawling Tools and APIs in 2026

  Contents# Crawling, Not Scraping# 1. Olostep# 2. Firecrawl# 3. ScrapeGraphAI# 4. Scrapling# 5. Crawl4AI# 6. Scrapy# 7. Crawlee# Final Thoughts # Crawling, Not Scraping  People often confuse web scraping with web crawling, but they are not the same thing. Web scraping usually means extracting content from a specific page. You give the tool a URL, and it returns the content from that page in …

7 Best Web Crawling Tools and APIs in 2026 Read More »

ai agents society of specialists.webp

AI Agents Point to a Society of Specialists, Not One AGI · Hanh D. Brown

AI Agents Point to a Society of Specialists, Not One AGI. A language model answers you. An agent goes and does the thing. The moment it can act, and hand work to other agents, the question stops being how clever it is. ai-agents human-in-the-loop prompt-injection cognitive-monoculture agi A language model answers your question. An agent …

AI Agents Point to a Society of Specialists, Not One AGI · Hanh D. Brown Read More »

open dictionary pen 226612 card

Building Document Structure with Loop Engineering: Recovering a PDF’s Outline from Body Typography for RAG

pipeline needs the document’s table of contents: retrieval scopes by section, and the chunker cuts on heading boundaries instead of mid-sentence. But some documents don’t have one. A paper exported straight from LaTeX has no native outline and no printed contents page, so there is no toc_df for the pipeline to read. The headings are …

Building Document Structure with Loop Engineering: Recovering a PDF’s Outline from Body Typography for RAG Read More »

the brief is the job.webp

The Real Skill in Building With AI Is Writing the Brief · Hanh D. Brown

The Real Skill in Building With AI Is Writing the Brief. There is a job now where the whole task is describing to a machine what to build, and the person doing it has never written code. The craft did not vanish. It moved. ai-tools clarity context-window product-judgment taste There is a job now where …

The Real Skill in Building With AI Is Writing the Brief · Hanh D. Brown Read More »

kdn chugani 7 approaches reduce inference latency llm workflows feature

7 Approaches to Reduce Inference Latency in Your LLM Workflows

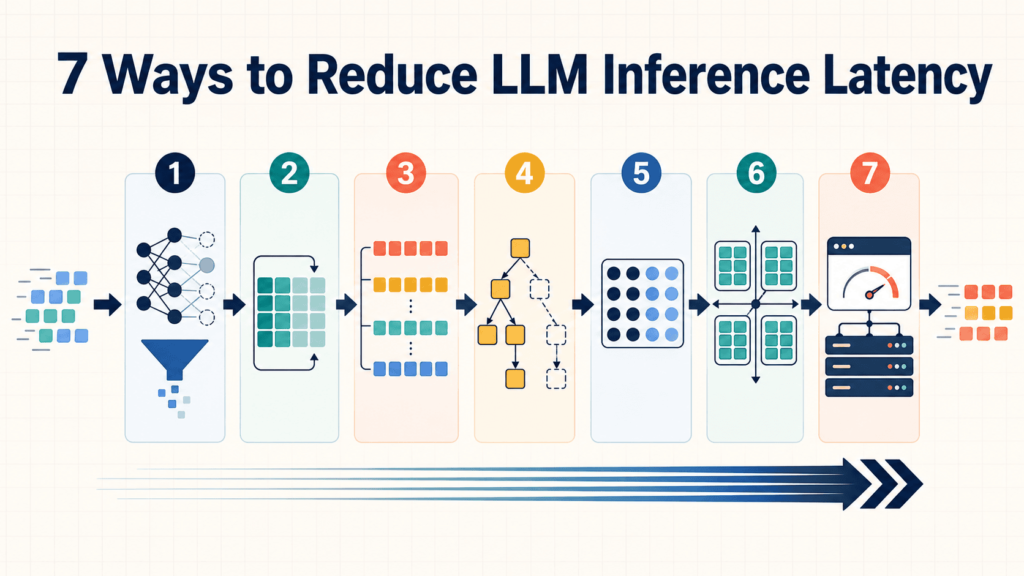
  Contents# Dealing With Inference Latency# 1. Implementing Model Quantization# 2. Utilizing Key-Value Caching# L3. everaging Speculative Decoding# 4. Transitioning to Continuous Batching# 5. Pruning and Distilling Your Models# 6. Deploying with Optimized Inference Engines# 7. Optimizing Context and Prompt Management# Stacking Optimizations in Practice # Dealing With Inference Latency  As large language models (LLMs) move from research prototypes into production, engineering teams run into …

7 Approaches to Reduce Inference Latency in Your LLM Workflows Read More »

one answer many models.webp

How an AI Agent Works at Scale · Hanh D. Brown

One Answer, Fifteen Models: How an AI Agent Works at Scale. Ask a production agent one question and a stopwatch starts. Two seconds. In that window it will run more models than most people think exist in the whole system. ai-agents reliability voice-ai agent-architecture outcome-pricing Ask a production agent one question and a stopwatch starts. …

How an AI Agent Works at Scale · Hanh D. Brown Read More »

Scroll to Top